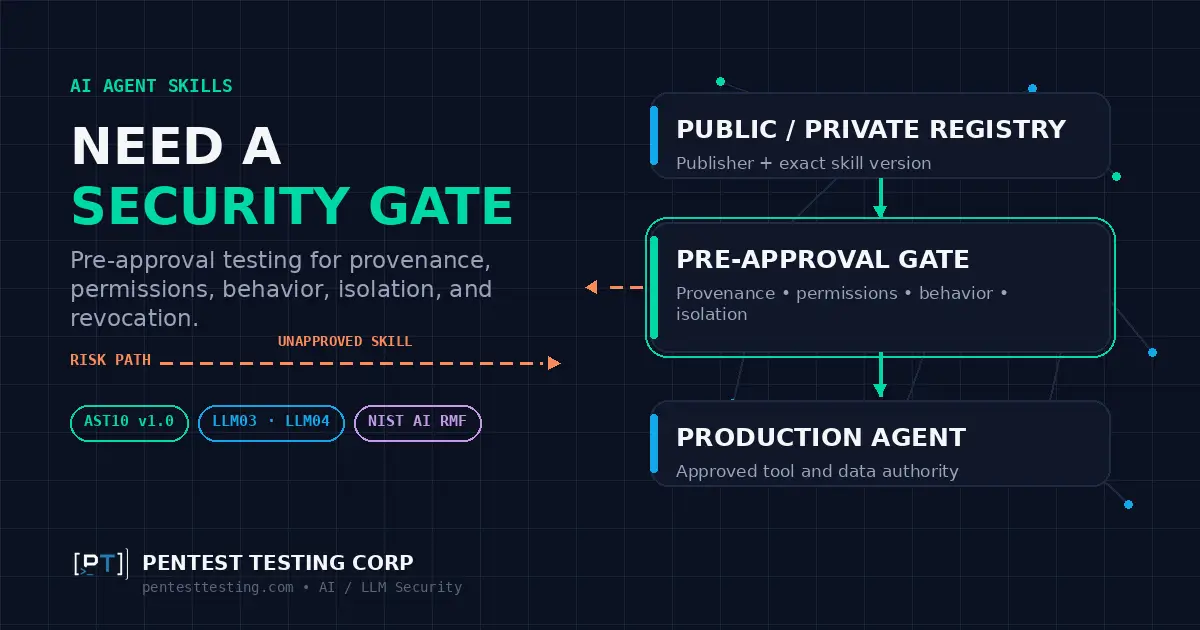
AI Agent Skill Security Testing: A Pre-Approval Plan After OWASP AST10 v1.0
A security team is asked to approve a third-party skill for a production AI agent. The skill comes from a public registry, its description matches the intended workflow, and an automated scanner reports no obvious problems. The agent, however, can read internal files, call business tools, use delegated credentials, reach external services, and complete multi-step actions on behalf of users.
That is no longer just a package-review decision. It is an AI agent skill security testing decision.
OWASP released version 1.0 of the Agentic Skills Top 10 on August 17, 2026, after malicious-skill activity had already demonstrated that reusable agent instructions pose supply-chain and execution risks. A USENIX Security 2026 study analyzed 98,380 skills from two major registries and confirmed that 157 skills exhibited malicious behavior, encompassing 632 distinct vulnerabilities across 13 attack techniques.
For CISOs, CTOs, AI platform owners, engineering leaders, and procurement teams, the implication is practical: approving a skill should require evidence about provenance, effective permissions, external instruction sources, runtime behavior, isolation, change control, logging, and revocation. A registry badge or successful scan can contribute to that decision, but it should not be the decision itself.
Why AI Agent Skill Security Testing Changed After AST10 v1.0
The security problem is easy to underestimate because an agent skill may look less complex than conventional software. Depending on the ecosystem, a skill can include a SKILL.md file or another manifest, natural-language instructions, scripts, resources, dependencies, external references, metadata, and platform-specific configuration.
The important difference is not the file format. It is what happens after the agent loads it.
A skill can influence which tools an agent selects, what information it retrieves, how it sequences several actions, which external sources it trusts, and what it attempts using the agent's existing permissions. In other words, natural-language instructions can participate in an execution path that eventually reaches files, APIs, cloud services, customer records, developer tools, or other business systems.
OWASP's AST10 v1.0 formalizes ten risks around that lifecycle:
- AST01: Malicious Skills
- AST02: Supply Chain Compromise
- AST03: Over-Privileged Skills
- AST04: Insecure Metadata
- AST05: Untrusted External Instructions
- AST06: Weak Isolation
- AST07: Update Drift
- AST08: Poor Scanning
- AST09: No Governance
- AST10: Cross-Platform Reuse
The framework arrived alongside evidence that this is not merely a theoretical design concern. OWASP's v1.0 release cites the January 2026 ClawHavoc campaign, which distributed 1,184 malicious skills from 12 publisher accounts. Separately, the USENIX Security 2026 research combined static analysis with dynamic behavioral verification across 98,380 collected skills and confirmed 157 malicious ones.
Those numbers should not be interpreted as a universal infection rate for every agent ecosystem. They do establish a more important point for enterprise buyers: public skill distribution now deserves the same kind of provenance, permission, lifecycle, and independent assurance questions that organizations already apply to other consequential third-party components.
For organizations operating agents with business-system access, AI penetration testing for tool-enabled and agentic systems should therefore include the skill layer when reusable skills can materially affect execution.
This layer is also distinct from MCP. An MCP security assessment evaluates the protocol and tool connection, including identities, authorization, servers, context, and downstream resources. A skill may sit above that connection and determine how several tools are orchestrated. Securing one layer does not automatically approve the other.
What a Pre-Approval Security Review Must Actually Prove
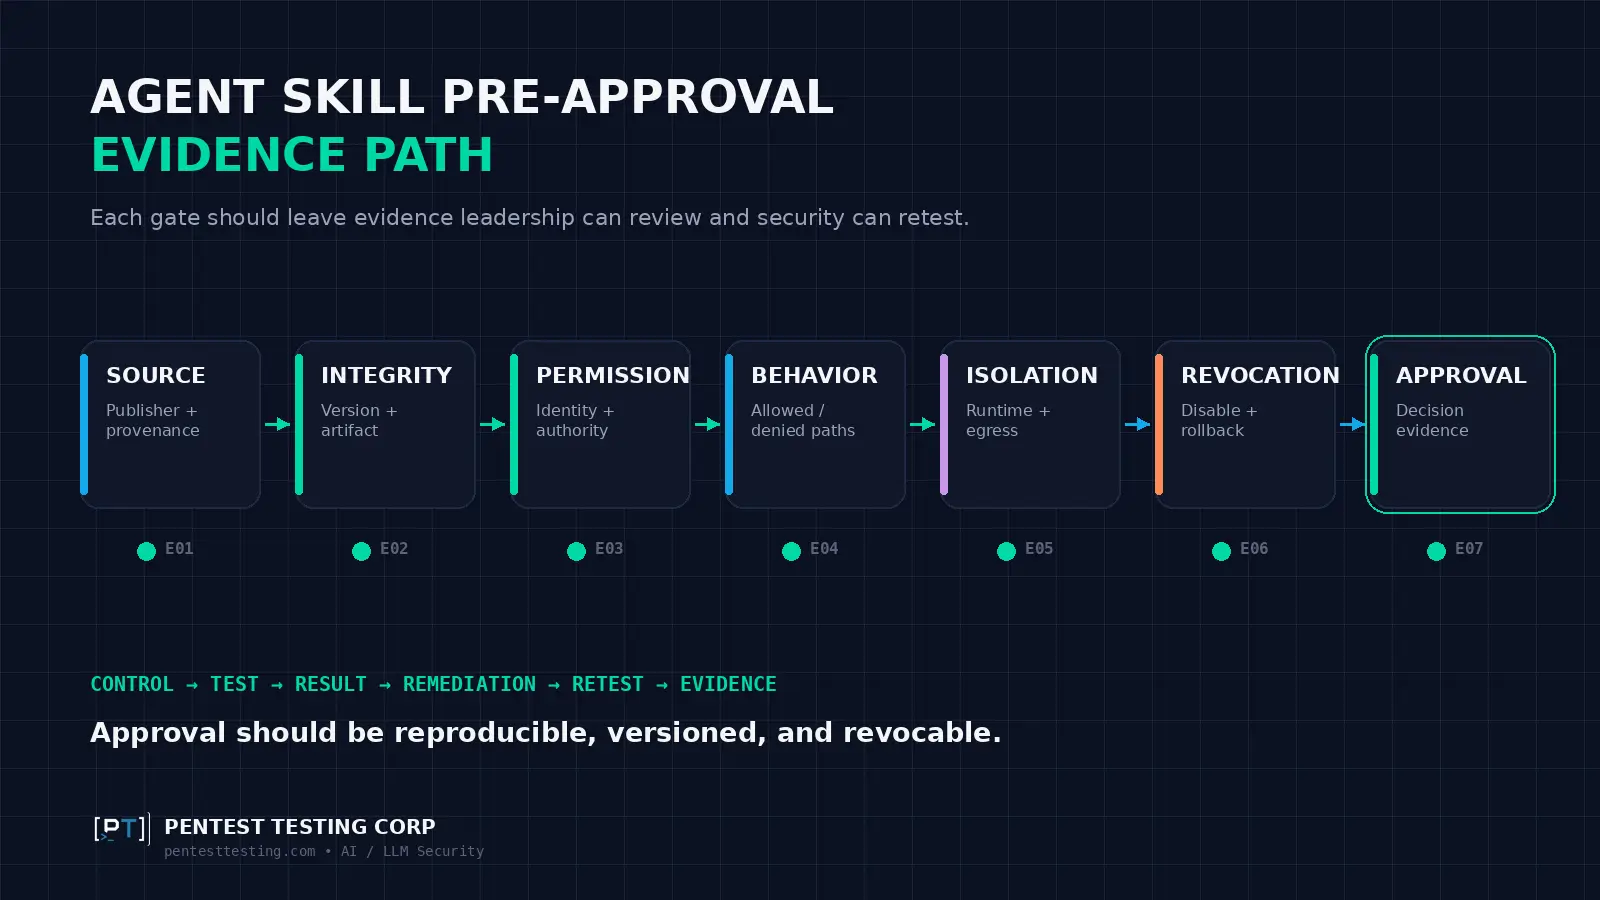
A useful approval process starts with business claims rather than ten framework labels. The security team should define what must be true before the skill is permitted in production and which evidence will support that conclusion.
| Approval question | Evidence leadership should require | Business failure being prevented | Typical remediation effort |
|---|---|---|---|
| Who published this exact version? | Publisher identity, source, version, integrity record, review date, and approval record | Impersonated, substituted, or unapproved components entering production | Low to medium where provenance tooling already exists |
| What can the skill actually access? | Effective permission and identity matrix covering files, tools, data, APIs, network access, and write actions | A low-risk workflow inheriting authority broader than its business purpose | Medium to high if shared privileged identities must be redesigned |
| Can behavior change after approval? | Inventory of external instructions, mutable repositories, dependencies, remote resources, and update paths | An approved local package later behaving differently without a new review | Medium, potentially high for heavily dynamic workflows |
| What contains unexpected behavior? | Runtime isolation, file restrictions, secret boundaries, egress controls, and environment separation | A compromised skill inheriting unnecessary host, network, or credential access | Medium to high where agents run on general-purpose infrastructure |
| Do prohibited actions actually fail? | Controlled allowed-versus-denied behavioral test results | A scanner reporting "pass" while the production workflow still crosses an authorization boundary | Depends on roles, tools, data boundaries, and workflow count |
| Can an incident be reconstructed? | Logs tying user, agent, skill version, identity, tool, action, target, result, and correlation data together | Security teams being unable to determine what a suspect skill did | Medium where agent telemetry is immature |
| Can the skill be stopped quickly? | Tested revocation, disable, rollback, credential rotation, and affected-agent identification process | An unsafe version remaining active because nobody can identify or remove it reliably | Low after governance tooling exists; higher when inventory is manual |
This table is more useful during procurement than asking whether a vendor "supports AST10." Framework coverage matters, but the buyer ultimately needs proof about the deployed architecture.
A particularly important distinction is between declared permissions and effective permissions. A manifest may say that a skill performs a narrow task, while the service account or runtime underneath it can access significantly more. Security decisions should be based on what the complete execution path can reach, not only what the skill claims it needs.
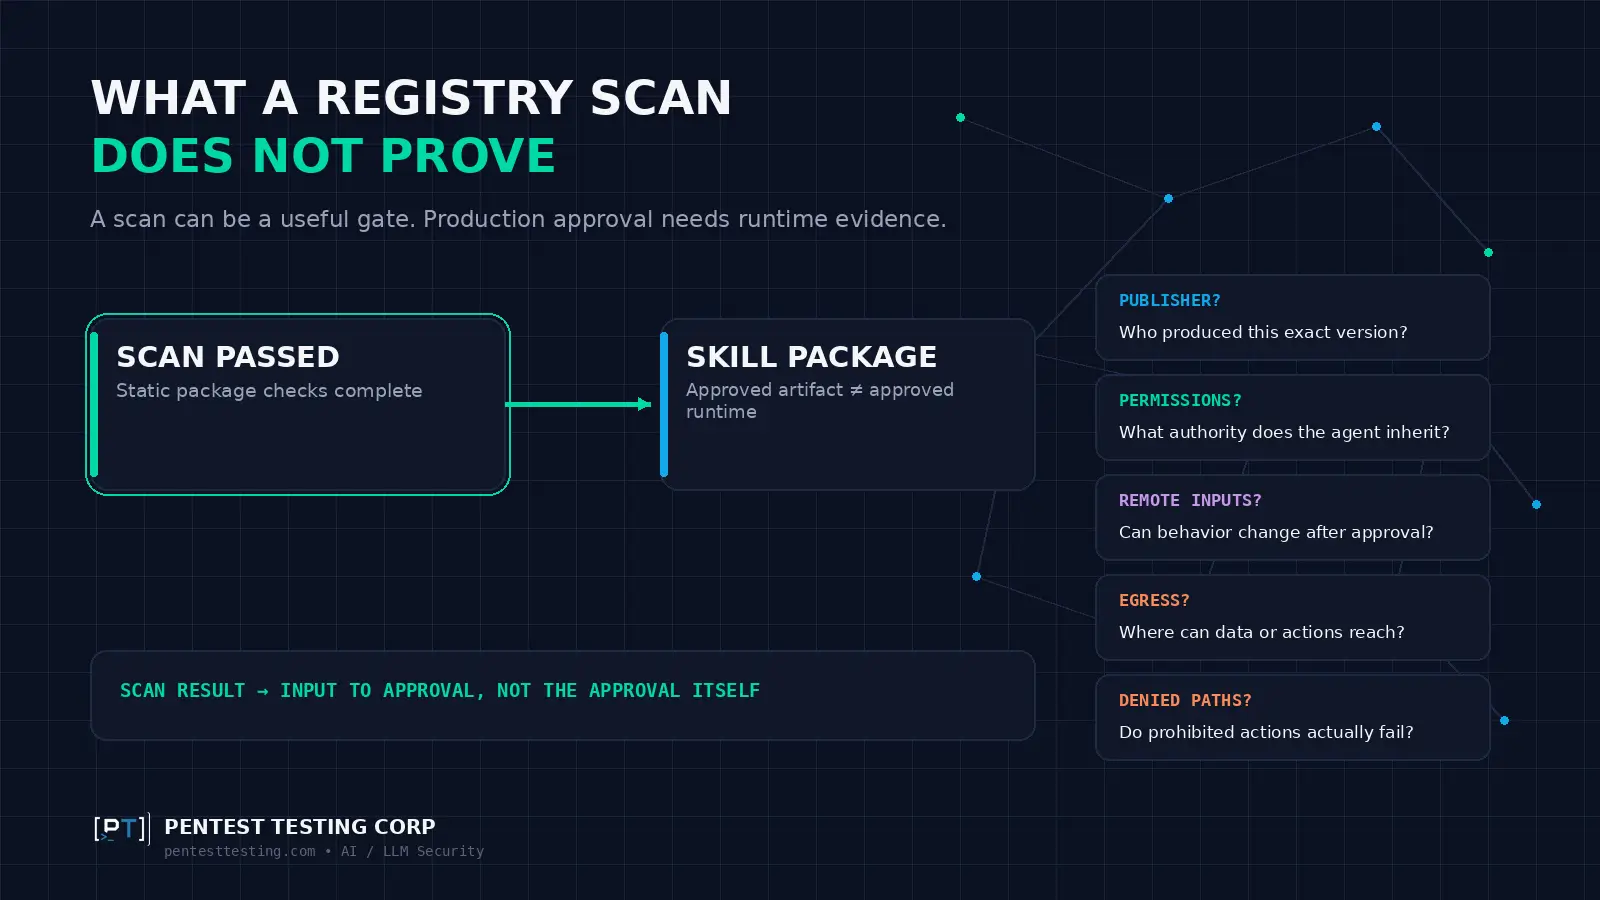
Why a Registry Scan Is a Gate, Not the Final Approval
Automated scanning remains useful. It can identify known malicious indicators, suspicious scripts, package issues, unsafe metadata patterns, dependencies, or other characteristics that should block a skill before it reaches a more expensive manual review.
The mistake is treating a successful scan as evidence of the entire runtime security posture.
The USENIX Security 2026 research is instructive because the researchers did not rely on one technique. Their methodology combined static pattern matching with dynamic behavioral verification. That reflects the underlying difficulty: malicious or unsafe behavior can span conventional code and natural-language instructions, while some consequences only become visible after a skill interacts with an agent, identity, tool, or environment.
A registry scan generally cannot answer all of the following questions by itself:
- Does the agent run the skill under an identity with more authority than the requesting user?
- Can the skill reach customer records, repositories, cloud resources, or files outside its intended scope?
- Does it depend on a remote instruction source that can change independently of the approved package?
- Does application-level authorization still block a prohibited action if the agent attempts it?
- Can a write-capable tool act without an appropriate human or deterministic approval gate?
- Does unrestricted network egress turn an otherwise contained problem into a data-exposure path?
- Can the organization locate every agent using the affected version and disable it quickly?
This does not mean every low-risk skill needs a full penetration test. It means the approval depth should increase with authority and business impact.
A read-only formatting skill operating on non-sensitive data in an isolated environment may be handled through provenance verification, scanning, permission review, and automated policy. A skill that can access regulated information, execute scripts, modify customer records, operate cloud resources, use privileged credentials, or orchestrate multiple write-capable tools deserves a substantially stronger pre-production review.
For a broader system-level scope, our guide to what an AI penetration test should cover shows how skills fit alongside prompts, RAG, models, APIs, identities, retrieval sources, infrastructure, and downstream tools.
What AI Agent Skill Security Testing Should Cover
A strong assessment follows the skill from acquisition through execution and eventual retirement. That keeps the work focused on identifiable control points rather than turning the engagement into an open-ended review of every AI component.
1. Inventory and accountable ownership
Begin with a reconciled inventory of production, staging, and development skills that can influence real workflows. Each entry should identify the skill, exact version, source, publisher, agent, environment, business purpose, data access, connected tools, and accountable owner.
This is partly a governance exercise, but it has direct incident consequences. A security team cannot revoke a malicious version quickly if it cannot determine where that version is running.
2. Publisher, provenance, and integrity
Review every permitted acquisition route: public registries, private registries, repositories, marketplace installs, uploaded archives, manually copied packages, and internally created skills.
The objective is to establish whether the organization can prove where a skill came from and whether the running artifact is the same artifact that was approved. Appropriate controls may include publisher verification, signatures, hashes, immutable versions, controlled repositories, dependency records, and documented exceptions.
Approval paths should also account for installation outside the normal registry workflow. A central policy is incomplete if a developer can bypass it through a local configuration directory, direct repository checkout, automation pipeline, or alternate tool.
3. Effective permissions and delegated identity
Permission review should start from the business task and work outward.
If a skill only needs to summarize support tickets, determine whether it truly requires broad CRM access, unrestricted file access, shell capabilities, write permissions, or open outbound connectivity. Where tools operate under a service account, assess whether that identity can reach more customers, tenants, projects, environments, or actions than the end user should be able to access.
This is where OWASP's agentic and LLM guidance converges around least privilege. The safest design assumes model behavior may sometimes be manipulated or simply wrong, then limits the impact through deterministic controls outside the model.
4. External instructions and mutable dependencies
A locally approved package may still obtain behavior from outside itself. The review should map every remote or mutable source that can influence what the skill does, including documentation, repositories, downloaded resources, packages, APIs, configuration, memory, shared instructions, and other dependencies.
The buyer question is straightforward: Can something change the skill's effective behavior without reopening the approval process?
If the answer is yes, the organization needs controls for pinning, validation, monitoring, integrity, or reassessment appropriate to the impact of that source.
5. Runtime isolation and egress
Testing should determine the maximum realistic blast radius if the skill becomes malicious, compromised, or manipulated by untrusted content.
Relevant boundaries may include process or container isolation, file-system restrictions, secret separation, tool allowlists, network destination controls, execution limits, environment separation, and different identities for user-level versus administrative operations.
The goal is not to prove that an AI system will never behave unexpectedly. The goal is to show that unexpected behavior does not automatically inherit unrestricted access to the surrounding environment.
6. Allowed and prohibited workflow testing
High-impact skills need controlled behavioral testing against both legitimate business paths and prohibited ones.
The test should answer whether the deployed system preserves user, tenant, object, data-class, tool, environment, and approval boundaries when the skill behaves unexpectedly. It should not depend on publishing exploit payloads or damaging production systems. Test accounts, synthetic data, controlled environments, rollback plans, and explicit rules of engagement should be used where actions could create material impact.
The meaningful result is not "the model followed an unusual instruction." The meaningful result is whether a protected business boundary remained enforced.
7. Updates, revocation, and retesting
Approval should apply to a defined artifact and deployment state, not indefinitely to a product name.
Material changes to the publisher, version, dependencies, external instruction sources, permissions, runtime, agent identity, connected tools, data access, or cross-platform packaging should trigger reassessment according to risk.
Security teams should also test the reverse path: identify the affected agents, block the unsafe version, stop reload, rotate credentials if necessary, restore a trusted version, and preserve evidence for investigation.
| Skill profile | Recommended review depth | Primary effort drivers |
|---|---|---|
| Low-impact, read-only skill | Inventory, provenance, scanning, permission validation, policy review | Number of sources, package variants, and environments |
| Skill with sensitive data or write-capable business tools | Full permission, identity, behavior, authorization, isolation, logging, and rollback validation | Roles, tenants, tools, data classes, approval flows, external instructions |
| Privileged or multi-tool autonomous skill | Independent agentic security assessment with prohibited-path testing and incident-control validation | Privileged identities, action combinations, environments, dependencies, network reach, business impact |
These profiles are scoping categories, not fixed prices or guaranteed timelines. Assessment effort should follow the architecture and authority of the deployed workflow rather than the number of AST10 rows in a checklist.
Hypothetical Scenario: The Skill Passed the Scan, but the Workflow Is Still Over-Privileged
The following example is hypothetical and does not describe a Pentest Testing Corp client.
A SaaS company deploys an AI support agent that reads tickets, searches an internal knowledge base, checks customer account information, and updates support cases. Engineering adds a third-party triage skill from a public registry because it improves classification and routing.
The package passes the registry's automated scan. The publisher appears legitimate. Procurement has already approved the underlying AI provider, and the MCP server connecting the agent to the support platform went through a separate security review.
Leadership assumes the new skill adds little incremental risk.
A pre-approval assessment identifies four issues:
- The installed skill references a remotely maintained instruction source that was not captured during the original package review.
- The agent's service identity can read support records across more customer groups than the employee using the workflow is permitted to access.
- The runtime environment has broad outbound connectivity because several unrelated integrations share the same host.
- The organization has no central record connecting the exact installed skill version with every production agent that loads it.
None of those conditions proves that data will be stolen or that the skill is malicious. Overstatement here would produce the wrong security decision.
Together, however, they create a credible control path worth addressing. A mutable external source can influence behavior after review. The agent has broader data access than the user needs. Network controls provide more destinations than the workflow requires. If a version later becomes unsafe, incident responders cannot immediately identify every affected deployment.
The appropriate remediation therefore crosses several teams:
- Platform engineering pins, internalizes, or otherwise controls the external instruction source.
- IAM and application teams reduce effective permissions and ensure downstream authorization follows the current user and tenant.
- Cloud or endpoint security restricts outbound destinations and isolates unrelated workloads.
- Security governance records the approved publisher, version, deployment locations, owner, and revocation procedure.
- The product or risk owner decides whether any remaining exception is acceptable for production.
This is why skill security is not purely a malware-scanning problem. It is a supply-chain, identity, authorization, runtime, and governance problem whose consequences depend on the authority of the agent that ultimately executes the workflow.
How AST10 Maps to OWASP Agentic, LLM, and NIST Guidance
AST10 should complement broader AI security frameworks rather than replace them.
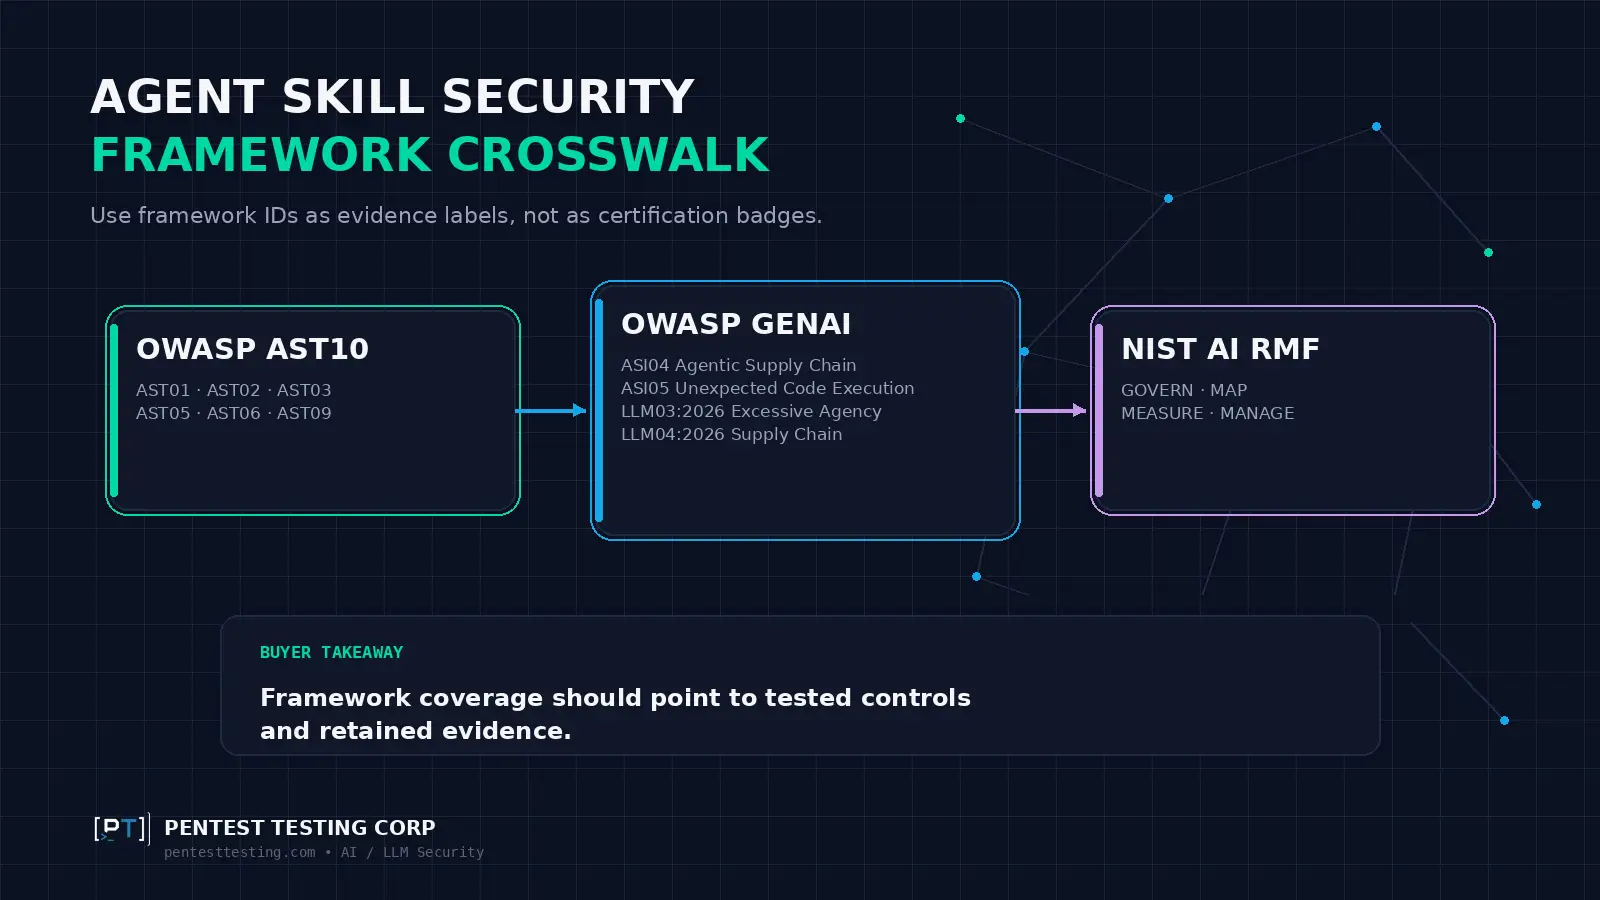
Framework versioning matters in September 2026. OWASP has now published the GenAI LLM Top 10 2026, which changes some identifiers used in 2025 documents. Organizations should therefore include the year whenever they cite an LLM category in reports, vendor questionnaires, test plans, or control mappings.
| Skill security theme | AST10 | OWASP Agentic mapping | Current OWASP LLM mapping | 2025 equivalent where relevant |
|---|---|---|---|---|
| Publisher, package, dependency, and registry trust | AST01, AST02, AST07, AST10 | ASI04 Agentic Supply Chain | LLM04:2026 Supply Chain | LLM03:2025 Supply Chain |
| Unnecessary tools, identities, permissions, and autonomy | AST03, AST06 | ASI03 Identity and Privilege Abuse | LLM03:2026 Excessive Agency | LLM06:2025 Excessive Agency |
| Instructions causing execution outside the intended workflow | AST01, AST05, AST06 | ASI05 Unexpected Code Execution | LLM01:2026 Prompt Injection and LLM03:2026 Excessive Agency where applicable | LLM01:2025 and LLM06:2025 |
| Inventory, approval, monitoring, and reassessment | AST08, AST09 | Multiple agentic governance controls | Supports security assurance across the applicable LLM risks | Same governance principle; identifiers depend on the tested failure |
LLM04:2026 Supply Chain
The current OWASP LLM Top 10 places Supply Chain at LLM04:2026. For organizations still using 2025 control matrices, the corresponding category was LLM03:2025.
Agent skills extend the supply-chain question beyond conventional libraries or model artifacts. The organization may need to govern publisher identity, manifests, natural-language instructions, bundled scripts, dependencies, remote content, registry provenance, update behavior, and the transformations that occur when a skill is moved between ecosystems.
LLM03:2026 Excessive Agency
Excessive Agency moved to LLM03:2026; in the 2025 edition it was LLM06:2025.
This is directly relevant to agent skill permission testing because a legitimate skill can still be unsafe when the host agent gives it unnecessary functionality, excessive permissions, or too much autonomous authority. Security should therefore evaluate the effective capabilities behind the skill rather than treating trust in the publisher as a substitute for least privilege.
ASI04 and ASI05
ASI04: Agentic Supply Chain provides the broader system-level view of third-party components, agent tooling, dependencies, and trust relationships. ASI05: Unexpected Code Execution becomes relevant when skills, scripts, hooks, generated commands, or instruction-driven workflows can lead to execution beyond the intended business path.
The mapping should not be interpreted as evidence that every skill issue automatically results in code execution. ASI05 applies only where the architecture and observed behavior support that connection.
NIST AI Risk Management Framework
The NIST AI Risk Management Framework remains useful for converting technical skill testing into management evidence. NIST currently states that AI RMF 1.0 is being updated, so reports should record which version they use rather than making an open-ended claim of "NIST compliance."
| NIST AI RMF function | Application to agent skills | Useful assessment evidence |
|---|---|---|
| GOVERN | Define ownership, permitted sources, approval policy, risk tiers, exceptions, and incident responsibility | Policy, inventory, approval workflow, ownership matrix |
| MAP | Identify skills, agents, users, identities, data, tools, dependencies, external instructions, and potential impact | Architecture map, trust boundaries, skill lifecycle, permission model |
| MEASURE | Evaluate provenance, permission boundaries, runtime behavior, isolation, security controls, and prohibited workflows | Test cases, findings, control-effectiveness evidence, limitations |
| MANAGE | Prioritize remediation, revoke unsafe versions, accept limited residual risk, monitor changes, and retest | Remediation register, risk acceptance, rollback results, retest evidence |
For a deeper governance crosswalk, see our AI pentest and NIST AI RMF mapping guide.
What Leadership Should Decide Before a Skill Is Approved
The technical team can test a skill, but leadership still owns several policy decisions that determine whether testing has meaningful boundaries.
1. Are agent skills governed as software or executable supply-chain content?
Skills should not fall outside change management simply because much of their behavior is expressed as text. If a component can influence the actions of an agent with real authority, it should have an owner, version, approval status, inventory record, and incident path.
2. Which sources are permitted?
Decide whether production agents may obtain skills from public registries, verified publishers, private registries, approved repositories, or internally packaged sources only. Document who can approve exceptions and how bypass routes are prevented.
3. Which skill capabilities automatically require independent testing?
Useful escalation triggers include confidential or regulated data access, write capabilities, shell or code execution, privileged identities, unrestricted network communication, mutable remote instructions, cross-tenant access, persistent memory changes, and orchestration of several sensitive tools.
4. What is the approval evidence threshold?
For a high-impact skill, leadership should normally require more than a scan result. Provenance, permission mapping, behavior testing, isolation results, logging evidence, revocation capability, remediation ownership, and retest criteria form a stronger approval package.
Organizations preparing for enterprise customer reviews can also use an AI red teaming vendor questionnaire to identify which artifacts procurement or security reviewers are likely to request.
5. Who can accept residual risk?
Engineering can explain feasibility and security can characterize exposure, but a business or product owner should be accountable for accepting material residual risk affecting customers, regulated information, financial operations, or other consequential workflows.
6. Which changes invalidate approval?
An approval should not silently survive material changes to the publisher, version, dependencies, external instruction sources, permission set, runtime environment, agent identity, connected tools, data access, or packaging format.
7. What are the possible go-live outcomes?
A practical decision model has three outcomes:
- Approve with evidence: Required controls are implemented and meaningful prohibited paths have been independently tested.
- Approve with time-bound conditions: Remaining issues have compensating controls, accountable owners, explicit deadlines, and defined retest requirements.
- Delay approval: A material provenance, permission, isolation, authorization, logging, or revocation weakness creates a blast radius outside the organization's tolerance.
The resulting assessment should leave behind artifacts that engineering can use to fix weaknesses and that leadership, procurement, or compliance teams can use to understand what was actually tested. Pentest Testing Corp's sample penetration testing reports show the broader reporting structure buyers should expect, including executive context, validated findings, technical evidence, remediation guidance, and retesting.
Frequently Asked Questions About AI Agent Skill Security Testing
Is the OWASP Agentic Skills Top 10 final?
OWASP released Agentic Skills Top 10 version 1.0 on August 17, 2026. Organizations should record the specific AST10 version used in assessments and governance documents because the agent-security ecosystem is still developing and future revisions are likely.
Is automated skill scanning enough before production approval?
No for high-impact skills. Automated scanning is an important first gate, but it does not necessarily prove effective permissions, downstream authorization, runtime isolation, mutable external instructions, user or tenant boundaries, incident logging, or revocation behavior. The required assurance depth should match the skill's business authority.
Does an MCP penetration test automatically cover agent skills?
No. MCP testing focuses on the protocol and tool boundary, including authentication, authorization, servers, identities, context, and downstream resources. Skill testing evaluates reusable workflow content that may select and orchestrate those tools, including provenance, permissions, dependencies, external instructions, updates, behavior, and revocation. Systems using both may need both layers in scope.
Which agent skills should receive independent security testing?
Prioritize skills that can access confidential or regulated information, perform write actions, use privileged or shared identities, execute scripts or commands, communicate externally, modify persistent state, load mutable instructions, cross tenant or account boundaries, or orchestrate multiple high-impact tools. Low-risk read-only skills may be suitable for a lighter risk-based review.
How often should an approved agent skill be reassessed?
Reassess after material changes to the skill version, publisher, dependency chain, permissions, runtime, identity, connected tools, data sources, external instructions, or packaging format. High-impact production workflows should also have periodic review because registries, dependencies, infrastructure, and threat information change after the initial approval.
Can a vendor questionnaire replace an AI agent skill security test?
No. A questionnaire can establish scope, governance expectations, architecture information, and evidence requirements, but it cannot independently demonstrate that prohibited actions fail in the deployed environment. Questionnaire responses are strongest when they point to actual test results, remediation records, and retest evidence.
What should an agent skill security assessment report contain?
The report should identify the exact skills and versions tested, source and provenance, environments, agents, identities, tools, permissions, external dependencies, relevant trust boundaries, allowed and prohibited workflow tests, validated findings, business impact, remediation, framework mappings, limitations, revocation results, and retest status. Sensitive implementation details should be handled under appropriate confidentiality controls.
Does passing AST10 mean an organization is compliant?
No. AST10 is a security risk framework, not a general compliance certification. Testing against it can provide evidence that supports an organization's AI governance, vendor review, risk management, and assurance activities, but compliance conclusions depend on the applicable framework, system boundary, contractual requirements, and organizational controls.
Conclusion
Agent skills should no longer be approved as harmless configuration merely because their visible interface is a markdown file or registry entry. Once a skill can influence an agent that holds real identities, tools, data access, network reach, or write authority, the approval question becomes whether the complete execution path is trustworthy and sufficiently contained.
OWASP AST10 v1.0 gives security teams a useful vocabulary for that layer. Current research adds evidence that malicious skills exist in public ecosystems at meaningful scale. Neither point means every third-party skill is malicious. They do mean that provenance, permission, behavior, isolation, logging, change control, and revocation should be explicit parts of enterprise approval.
If your organization is establishing a skill registry, preparing a tool-enabled AI agent for production, responding to an enterprise security review, or reassessing existing agent integrations, request an agentic AI security assessment from Pentest Testing Corp. The assessment can be scoped around the skills, agents, identities, tools, data boundaries, environments, and evidence your approval process actually needs.